124. Linear Quadratic Mean Field Games#
124.1. Overview#
A mean field game describes a continuum of small agents, each of whom solves a dynamic optimization problem whose payoff depends on what everybody else is doing, summarized by the cross-sectional distribution of states.
The framework was introduced by Lasry and Lions [2007] and, independently, by Huang et al. [2006].
It pairs two partial differential equations:
a Hamilton-Jacobi-Bellman equation that runs backward in time and describes an individual’s optimal choice, given paths for the aggregates
a Kolmogorov forward equation that runs forward in time and describes how the distribution of individual states evolves, given those choices
An equilibrium requires that the aggregates that agents take as given are the ones that their own decisions generate.
The same pair of equations is the workhorse of continuous-time heterogeneous-agent macroeconomics; see Achdou et al. [2022].
Readers of Rational Expectations Equilibrium will recognize that requirement.
It is the “Big \(Y\), little \(y\)” idea, now applied to an entire distribution rather than to a single number.
This lecture studies a tractable special case in which the payoff is quadratic and the state evolves linearly, following Alvarez and Argente [2026].
Two kinds of interaction appear:
agents care about the cross-sectional average state \(X\), through a matrix \(\Theta_X\)
agents care about the cross-sectional average action \(\mathcal A\), through a matrix \(\Theta_{\mathcal A}\)
The main result is a striking simplification:
Note
The equilibrium of the mean field game solves the algebraic Riccati equation of a single-agent linear quadratic regulator problem, in which the curvature matrices \(Q\) and \(\Gamma\) are replaced by
Everything we know about the linear regulator can therefore be brought to bear on the equilibrium: existence conditions, uniqueness, comparative statics, and numerical methods.
We then put the framework to work on two economic examples from Alvarez and Argente [2026]: an industry equilibrium with capital accumulation, and a multiproduct pricing problem with Kimball demand.
Riccati equations appear in several other QuantEcon lectures:
LQ Control: Foundations introduces the linear regulator and its Riccati equation
Lagrangian for LQ Control studies the state-costate system and its stable invariant subspace, which is exactly the structure we meet below
Markov Perfect Equilibrium studies dynamic games with finitely many players, where each player has a Riccati equation and the equations are coupled
A First Look at the Kalman Filter presents the Riccati equation that is dual to the control problem
Let’s start with some imports:
import numpy as np
import matplotlib.pyplot as plt
from scipy.linalg import solve_continuous_are, expm
124.2. The environment#
There is a continuum of agents.
An individual has state \(x \in \mathbb R^n\) and takes an action \(\alpha \in \mathbb R^k\).
The cross-sectional average state and action are
where \(m\) is the density of the state across agents.
The period return is quadratic in all four objects:
The individual state follows
where \(W\) is an \(n\)-dimensional Brownian motion and shocks are purely idiosyncratic for now.
Agents discount at rate \(\rho > 0\).
We assume that \(Q\) and \(\Gamma\) are positive definite, that \(\Sigma\) is positive semi-definite, that \(B\) has full row rank, and that \(\Theta_X\) and \(\Theta_{\mathcal A}\) are symmetric.
124.2.1. Complements and substitutes#
From (124.1), the cross derivative between an agent’s own state and the average state is \(-\Theta_X\), and between her own action and the average action it is \(-\Theta_{\mathcal A}\).
So
states are strategic complements when \(-\Theta_X\) is positive definite, i.e. when \(\Theta_X\) is negative definite
states are strategic substitutes when \(\Theta_X\) is positive definite
and similarly for actions.
In the Loewner ordering, smaller \(\Theta\) means more complementarity.
Note
The monotonicity condition that Lasry and Lions [2007] impose to obtain uniqueness corresponds here to \(-\Theta_X\) being negative semi-definite, that is, to strategic substitutability in states.
We will not need it: in this linear quadratic setting there is at most one equilibrium whether interactions are complements or substitutes.
124.2.2. Equilibrium#
Taking the paths \(\{X(t), \mathcal A(t)\}\) as given, an agent’s value function satisfies the HJB equation
where the Hamiltonian is
with maximizer \(\alpha_*(p,\mathcal A) = \Gamma^{-1}(B^\top p - \Theta_{\mathcal A}\mathcal A)\).
The density evolves according to the Kolmogorov forward equation
and an equilibrium is a value function, a density, and paths for \(X\) and \(\mathcal A\) that satisfy (124.3), (124.4), and the consistency requirements that \(X\) and \(\mathcal A\) really are the cross-sectional averages implied by \(m\) and by the optimal policy.
124.3. Solving the individual problem#
Given the aggregate paths, an individual faces a time-varying linear quadratic regulator problem, so her value function is quadratic:
Substituting into (124.3) and matching terms of each order gives three differential equations.
The one for \(\beta_2\) is
Notice what is absent from (124.5): neither interaction matrix appears.
The curvature of an individual’s value function is therefore the same as it would be if she were alone in the world.
Because the individual problem is concave and stationary, \(\beta_2(t)\) equals the constant \(\bar\beta_2\), the negative definite solution of
This is the familiar algebraic Riccati equation of LQ Control: Foundations, written in continuous time.
The optimal action is
Averaging across agents and solving the resulting fixed point in \(\mathcal A\) gives
Equation (124.7) is where the action interaction first bites: each agent responds to the average action, and solving for the average that is consistent with everyone doing so replaces \(\Gamma\) by \(\Gamma + \Theta_{\mathcal A}\).
124.4. A state-costate system#
Two objects now remain: the linear coefficient \(\beta_1(t)\) of the value function, and the aggregate state \(X(t)\).
Differentiating and aggregating gives a pair of linear differential equations,
where we abbreviate
This is a state-costate system of exactly the kind studied in Lagrangian for LQ Control.
The aggregate state \(X\) has an initial condition, namely the mean of the initial distribution.
The costate \(\beta_1\) does not: it must be chosen so that the solution does not violate the agent’s transversality condition, which here requires the eigenvalues governing the path to have real parts below \(\rho/2\).
Because \(\Theta_X\), \(B\Gamma^{-1}B^\top\) and \(\Lambda\) are symmetric, \(\mathcal H - \tfrac\rho2 I\) is a Hamiltonian matrix, so its eigenvalues are symmetric about the origin.
Equivalently:
Proposition 124.1
If \(\lambda\) is an eigenvalue of \(\mathcal H\), then so are \(\rho - \lambda\), \(\bar\lambda\), and \(\rho - \bar\lambda\).
Exactly \(n\) eigenvalues can therefore have real parts below \(\rho/2\), which pins down a unique stable invariant subspace and hence at most one equilibrium.
This is the standard connection between algebraic Riccati equations and invariant subspaces of Hamiltonian matrices, treated at length by Lancaster and Rodman [1995].
124.5. The equilibrium Riccati equation#
We look for a saddle path along which the costate is a linear function of the state, \(\beta_1(t) = S X(t)\).
Substituting into (124.8) gives a quadratic matrix equation for \(S\) whose coefficients involve \(\bar\beta_2\).
That equation looks forbidding, but a change of variable transforms it.
Define
Proposition 124.2
An equilibrium is characterized by a matrix \(P\) solving
with aggregate dynamics
The equilibrium requires all eigenvalues of the closed-loop matrix to have real parts below \(\rho/2\).
Compare this with the single-agent equation (124.6).
They have the same form.
The only difference is that \(Q\) has become \(Q + \Theta_X\) and \(\Gamma\) has become \(\Gamma + \Theta_{\mathcal A}\).
Proposition 124.3
The equilibrium of a linear quadratic mean field game with interaction matrices \(\Theta_X\) and \(\Theta_{\mathcal A}\), and its aggregate law of motion, coincide with the solution of a single-agent linear quadratic control problem whose state curvature is \(Q+\Theta_X\) and whose action curvature is \(\Gamma+\Theta_{\mathcal A}\).
This is the organizing result of the lecture.
It says that strategic interaction does not change the form of the problem that determines aggregate dynamics; it changes the curvatures that enter it.
An immediate economic implication is that two models with very different strategic interactions can generate identical aggregate dynamics, provided the effective curvatures agree.
124.5.1. Existence and uniqueness#
Since \(P\) solves a standard Riccati equation, standard conditions apply.
Define
Proposition 124.4
Suppose \(B(\Gamma+\Theta_{\mathcal A})^{-1}B^\top\) is invertible.
A necessary condition for an equilibrium is that \(E\) be positive semi-definite.
If \(Q + \Theta_X\) and \(\Gamma + \Theta_{\mathcal A}\) are positive definite, an equilibrium exists and is unique.
There is at most one equilibrium.
The sufficient condition has a clean reading: effective curvature must remain positive in both states and actions.
Complementarity is therefore permissible, but only up to a point.
Notice also that the two interactions enter \(E\) additively, so substitutability in actions can offset complementarity in states.
124.6. Computing equilibria#
scipy.linalg.solve_continuous_are(A, B, Q, R) returns the stabilizing solution \(\tilde P\) of
Our equation differs in two ways: our \(P\) is negative definite, and we discount.
Writing \(P = -\tilde P\) and collecting terms shows that our equation is the standard one with \(A\) replaced by \(-(A + \tfrac\rho2 I)\).
The discount rate enters exactly as it does in the “\(\rho/2\) shift” familiar from continuous-time control.
def mfg_riccati(A, B, Q, Γ, ρ):
    """
    Solve  P B Γ^{-1} B' P = Q + ρ P + P A + A' P  for the negative
    definite stabilizing solution P.

    Passing Q + Θ_X and Γ + Θ_A gives the equilibrium of the mean field game;
    passing Q and Γ gives the single agent's value function curvature.
    """
    n = A.shape[0]
    return -solve_continuous_are(-(A + ρ/2 * np.eye(n)), B, Q, Γ)

def closed_loop(A, B, Γ_eff, P):
    "The matrix governing aggregate dynamics, Ẋ = (B Γ_eff^{-1} B' P - A) X."
    return B @ np.linalg.solve(Γ_eff, B.T) @ P - A
Let’s set up a two-dimensional example with complementarity in states and substitutability in actions, the configuration that Alvarez and Argente [2026] obtain from an industry equilibrium with capital accumulation.
ρ = 0.05
A = np.array([[0.4, 0.1],
              [0.0, 0.3]])
B = np.eye(2)
Q = np.array([[1.0, 0.2],
              [0.2, 0.8]])
Γ = np.array([[1.0, 0.1],
              [0.1, 1.2]])
Θ_X = np.array([[-0.3, 0.05],     # negative definite: complements in states
                [0.05, -0.2]])
Θ_A = np.array([[0.2, 0.0],       # positive definite: substitutes in actions
                [0.0, 0.1]])

β2 = mfg_riccati(A, B, Q, Γ, ρ)                 # single agent
P = mfg_riccati(A, B, Q + Θ_X, Γ + Θ_A, ρ)      # equilibrium

print("individual curvature β̄₂ =\n", β2.round(4))
print("\nequilibrium matrix P =\n", P.round(4))
individual curvature β̄₂ =
 [[-0.6614 -0.0869]
 [-0.0869 -0.654 ]]

equilibrium matrix P =
 [[-0.5353 -0.134 ]
 [-0.134  -0.5337]]
Let’s verify that \(P\) really does solve the equilibrium Riccati equation, and compare the aggregate dynamics with what a lone agent would choose.
Λ = B @ np.linalg.solve(Γ + Θ_A, B.T)
residual = P @ Λ @ P - (Q + Θ_X + ρ*P + P @ A + A.T @ P)
print(f"Riccati residual: {np.abs(residual).max():.2e}")

G = closed_loop(A, B, Γ, β2)          # dynamics without any interaction
JG = closed_loop(A, B, Γ + Θ_A, P)    # equilibrium dynamics

print("\neigenvalues without interactions:", np.linalg.eigvals(G).round(4))
print("eigenvalues in equilibrium:       ", np.linalg.eigvals(JG).round(4))
Riccati residual: 5.55e-17

eigenvalues without interactions: [-1.0698 -0.8321]
eigenvalues in equilibrium:        [-0.9025 -0.6423]
The equilibrium eigenvalues are closer to zero, so aggregate adjustment is slower than it would be if each agent ignored everyone else.
124.6.1. Checking the Hamiltonian structure#
Proposition 124.1 says the eigenvalues of \(\mathcal H\) come in pairs \(\{\lambda, \rho - \lambda\}\), and that the \(n\) eigenvalues with real parts below \(\rho/2\) are the ones that govern equilibrium dynamics.
Let’s check both claims.
BΓB = B @ np.linalg.solve(Γ, B.T)
n = A.shape[0]

H = np.block([[ρ*np.eye(n) + A.T - β2 @ Λ, Θ_X + β2 @ (BΓB - Λ) @ β2],
              [Λ,                          -A + Λ @ β2]])

ev = np.linalg.eigvals(H)
print("eigenvalues of ℋ:", np.sort(ev.real).round(4))
print("paired as λ and ρ - λ:",
      np.allclose(np.sort(ev.real), np.sort(ρ - ev.real)))

stable = np.sort(ev.real[ev.real < ρ/2])
print("\nstable half of ℋ:      ", stable.round(4))
print("closed-loop eigenvalues:", np.sort(np.linalg.eigvals(JG).real).round(4))
eigenvalues of ℋ: [-0.9025 -0.6423  0.6923  0.9525]
paired as λ and ρ - λ: True

stable half of ℋ:       [-0.9025 -0.6423]
closed-loop eigenvalues: [-0.9025 -0.6423]
The saddle path is the stable invariant subspace of \(\mathcal H\), exactly as in Lagrangian for LQ Control.
124.7. The scalar case#
With \(n = k = 1\) everything is explicit.
Write \(q, a, b, \gamma, \theta_X, \theta_{\mathcal A}\) for the scalars.
The Riccati equation becomes a quadratic, and the admissible root gives the aggregate eigenvalue
An equilibrium exists if and only if the term under the square root is positive,
and the equilibrium is stable, meaning \(\lambda<0\), if and only if
Formula (124.10) displays the two comparative statics at a glance.
More complementarity in states (a smaller \(\theta_X\)) raises \(\lambda\) and makes aggregate dynamics more persistent: when others stay away from the steady state, each agent has less reason to return to it.
More complementarity in actions (a smaller \(\theta_{\mathcal A}\)) lowers \(\lambda\) and makes dynamics less persistent: when others adjust, each agent wants to adjust too.
Let’s confirm that our solver reproduces (124.10).
def scalar_lambda(ρ, a, b, q, γ, θ_X, θ_A):
    "Closed-form aggregate eigenvalue in the scalar case."
    return ρ/2 - np.sqrt((ρ/2 + a)**2 + b**2*(q + θ_X)/(γ + θ_A))

ρ_s, a, b, q, γ = 0.05, 0.3, 1.0, 1.0, 1.0

print(f"{'θ_X':>6}{'θ_A':>6}{'solver':>12}{'closed form':>14}")
for θ_X, θ_A in ((0.0, 0.0), (-0.5, 0.0), (0.0, 0.5), (-0.5, 0.5)):
    P_s = mfg_riccati(np.array([[a]]), np.array([[b]]),
                      np.array([[q + θ_X]]), np.array([[γ + θ_A]]), ρ_s)
    λ_num = closed_loop(np.array([[a]]), np.array([[b]]),
                        np.array([[γ + θ_A]]), P_s)[0, 0]
    print(f"{θ_X:>6}{θ_A:>6}{λ_num:>12.6f}{scalar_lambda(ρ_s,a,b,q,γ,θ_X,θ_A):>14.6f}")
   θ_X   θ_A      solver   closed form
   0.0   0.0   -1.026487     -1.026487
  -0.5   0.0   -0.753219     -0.753219
   0.0   0.5   -0.853801     -0.853801
  -0.5   0.5   -0.637539     -0.637539
124.8. An industry equilibrium with capital accumulation#
The scalar model is not a toy.
Alvarez and Argente [2026] show that it describes an industry equilibrium with capital accumulation in which both kinds of interaction appear, with opposite signs.
There is a continuum of monopolistically competitive firms.
A firm with capital \(k\) produces \(y = k^\nu\) with \(0 < \nu < 1\), and a constant returns sector aggregates the differentiated goods with elasticity of substitution \(\eta > 1\).
With the final good as numeraire, a firm that produces \(y\) when industry output is \(Y\) earns revenue proportional to \(y^{1-1/\eta}Y^{1/\eta}\).
So if all other firms hold capital \(K\), operating profit is proportional to
Capital evolves according to
the firm buys investment goods at price \(\mathcal P(I)\), where \(I\) is aggregate investment, and it pays a convex adjustment cost \(\psi(i)\).
Let \(\bar i = \delta \bar k\) be steady-state investment, normalize \(\mathcal P(\bar i) = 1\) and \(\psi'(\bar i) = 0\), and write percentage deviations from the deterministic steady state as
A second-order expansion of the return around the steady state, with the objective normalized by \(\bar\Pi \equiv \Pi(\bar k, \bar k)\), delivers exactly (124.1) with
while the state equation becomes \(dx = \delta(\alpha - x)dt + \sigma dW\) to first order, so that
Differentiating (124.13) gives closed forms:
Three features of (124.14) deserve emphasis.
First, \(\theta_X < 0\): capital stocks are strategic complements, because a larger industry capital stock raises the demand shifter \(Y^{1/\eta}\) and hence the marginal profitability of a firm’s own capital.
Second, if the supply of investment goods slopes upward then \(\mathcal P'(\bar i) > 0\) and so \(\theta_{\mathcal A} > 0\): investment rates are strategic substitutes, because everyone investing at once bids up the price of capital goods.
Third, \(q + \theta_X > 0\) for every \(\eta > 1\) and every \(\nu \in (0,1)\), so by Proposition 124.4 an equilibrium exists and is unique no matter how strong market power is and no matter how close returns to scale come to constant.
Let’s put these formulas into code, and check them against numerical derivatives of the profit function itself.
def cap_q(η, ν):
    "Own-state curvature in the capital accumulation example."
    return ν*(η - 1)/η**2*(η*(1 - ν) + ν)

def cap_θ_X(η, ν):
    "State interaction in the capital accumulation example."
    return -(η - 1)/η*ν**2/η

η_c, ν_c = 4.0, 0.7

Π = lambda k, K: k**(ν_c*(1 - 1/η_c))*K**(ν_c/η_c)

h = 1e-5
Π_kk = (Π(1+h, 1) - 2*Π(1, 1) + Π(1-h, 1))/h**2
Π_kK = (Π(1+h, 1+h) - Π(1+h, 1-h) - Π(1-h, 1+h) + Π(1-h, 1-h))/(4*h**2)

print(f"{'':>10}{'finite difference':>20}{'closed form':>15}")
print(f"{'q':>10}{-Π_kk/Π(1, 1):>20.6f}{cap_q(η_c, ν_c):>15.6f}")
print(f"{'θ_X':>10}{-Π_kK/Π(1, 1):>20.6f}{cap_θ_X(η_c, ν_c):>15.6f}")
print(f"{'q + θ_X':>10}{-(Π_kk + Π_kK)/Π(1, 1):>20.6f}"
      f"{(η_c - 1)/η_c*ν_c*(1 - ν_c):>15.6f}")
             finite difference    closed form
         q            0.249374       0.249375
       θ_X           -0.091875      -0.091875
   q + θ_X            0.157499       0.157500
124.8.1. Calibration#
Take annual units, \(\delta = 0.10\), \(\rho = 0.05\), an elasticity of substitution \(\eta = 4\), and returns to scale \(\nu = 0.7\).
For the two curvatures that the technology does not pin down we set \(\gamma = 0.05\), which makes a firm that ignores the industry close half of a capital gap in three years, and \(\theta_{\mathcal A} = 0.09\).
Exercise 124.5 derives both numbers from an adjustment cost function and an investment supply curve.
ρ_c, δ_c = 0.05, 0.10
γ_c, θ_A_c = 0.05, 0.09

q_c, θ_X_c = cap_q(η_c, ν_c), cap_θ_X(η_c, ν_c)

def half_life(λ):
    "Time for the aggregate state to close half of a gap."
    return np.log(2)/(-λ)

λ_c = scalar_lambda(ρ_c, δ_c, δ_c, q_c, γ_c, θ_X_c, θ_A_c)

P_c = mfg_riccati(np.array([[δ_c]]), np.array([[δ_c]]),
                  np.array([[q_c + θ_X_c]]), np.array([[γ_c + θ_A_c]]), ρ_c)
λ_c_solver = closed_loop(np.array([[δ_c]]), np.array([[δ_c]]),
                         np.array([[γ_c + θ_A_c]]), P_c)[0, 0]

print(f"q = {q_c:.4f},  θ_X = {θ_X_c:.4f},  q + θ_X = {q_c + θ_X_c:.4f}")
print(f"λ from the solver      = {λ_c_solver:.6f}")
print(f"λ from the closed form = {λ_c:.6f}")
print(f"half-life of aggregate capital = {half_life(λ_c):.2f} years")
q = 0.2494,  θ_X = -0.0919,  q + θ_X = 0.1575
λ from the solver      = -0.138936
λ from the closed form = -0.138936
half-life of aggregate capital = 4.99 years
124.8.2. How much do the interactions matter?#
Because (124.10) depends on \(\theta_X\) and \(\theta_{\mathcal A}\) separately, we can switch each interaction off and read the answer.
cases = {'no interactions':            (0.0,     0.0),
         'state complementarity only': (θ_X_c,   0.0),
         'action substitutability only': (0.0,   θ_A_c),
         'equilibrium':                (θ_X_c,   θ_A_c),
         'planner (both doubled)':     (2*θ_X_c, 2*θ_A_c)}

print(f"{'':>30}{'λ':>10}{'half-life':>12}")
for label, (tx, ta) in cases.items():
    λ_case = scalar_lambda(ρ_c, δ_c, δ_c, q_c, γ_c, tx, ta)
    print(f"{label:>30}{λ_case:>10.4f}{half_life(λ_case):>12.2f}")
                                       λ   half-life
               no interactions   -0.2309        3.00
    state complementarity only   -0.1921        3.61
  action substitutability only   -0.1579        4.39
                   equilibrium   -0.1389        4.99
        planner (both doubled)   -0.1109        6.25
Both interactions slow aggregate capital adjustment, and they do so for different reasons.
Complementarity in states means that a firm has less reason to rebuild its capital while the rest of the industry is still below its steady state.
Substitutability in actions means that a burst of industry investment is expensive, so firms spread their investment over time.
Together they stretch the half-life of the industry’s capital stock from three years to five.
The planner, who internalizes both externalities, is slower still.
124.8.3. Micro and macro adjustment speeds#
A distinctive prediction of the model is that individual capital reverts to the mean faster than aggregate capital does, because (124.6) contains no interaction matrix.
β2_c = mfg_riccati(np.array([[δ_c]]), np.array([[δ_c]]),
                   np.array([[q_c]]), np.array([[γ_c]]), ρ_c)
λ_micro = closed_loop(np.array([[δ_c]]), np.array([[δ_c]]),
                      np.array([[γ_c]]), β2_c)[0, 0]

print(f"individual half-life = {half_life(λ_micro):.2f} years")
print(f"aggregate  half-life = {half_life(λ_c):.2f} years")
print(f"ratio                = {half_life(λ_c)/half_life(λ_micro):.2f}")
individual half-life = 3.00 years
aggregate  half-life = 4.99 years
ratio                = 1.66
A researcher who estimated the speed of capital adjustment from firm-level data, and then used it to predict how quickly the industry responds to an industry-wide shock, would be too fast by two thirds.
The gap is a pure interaction effect: the same technology and the same adjustment costs generate both numbers.
124.8.4. Market power and returns to scale#
How does the industry’s adjustment speed depend on the two technological parameters?
Both enter only through \(q + \theta_X = \frac{\eta-1}{\eta}\nu(1-\nu)\), which rises with \(\eta\) and is maximized at \(\nu = 1/2\).
η_grid = np.linspace(1.2, 12, 200)
ν_grid = np.linspace(0.05, 0.995, 200)

def macro_micro(η, ν):
    "Aggregate and individual half-lives as functions of (η, ν)."
    q, θ_X = cap_q(η, ν), cap_θ_X(η, ν)
    λ_agg = scalar_lambda(ρ_c, δ_c, δ_c, q, γ_c, θ_X, θ_A_c)
    λ_ind = scalar_lambda(ρ_c, δ_c, δ_c, q, γ_c, 0.0, 0.0)
    return half_life(λ_agg), half_life(λ_ind)

fig, axes = plt.subplots(1, 2, figsize=(11, 4.2))

hl_agg, hl_ind = np.array([macro_micro(η, ν_c) for η in η_grid]).T
axes[0].plot(η_grid, hl_agg, lw=2, label='industry')
axes[0].plot(η_grid, hl_ind, lw=2, ls='--', label='single firm')
axes[0].set_xlabel('elasticity of substitution $\\eta$')

hl_agg, hl_ind = np.array([macro_micro(η_c, ν) for ν in ν_grid]).T
axes[1].plot(ν_grid, hl_agg, lw=2, label='industry')
axes[1].plot(ν_grid, hl_ind, lw=2, ls='--', label='single firm')
axes[1].axhline(np.log(2)/δ_c, color='k', lw=1, alpha=0.6)
axes[1].set_xlabel('returns to scale $\\nu$')
axes[1].annotate('$\\ln 2/\\delta$', (0.12, np.log(2)/δ_c - 0.45))

for ax in axes:
    ax.set_ylabel('half-life in years')
    ax.legend()
plt.tight_layout()
plt.show()
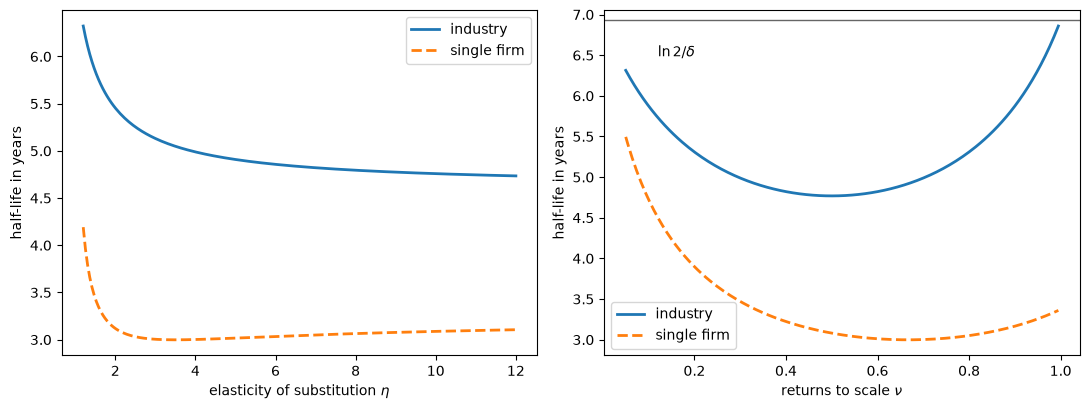
Fig. 124.1 Half-lives of industry and firm capital#
More market power, meaning a smaller \(\eta\), makes the industry slower: it weakens the own-capital curvature relative to the interaction, and the left panel shows the industry half-life rising as \(\eta\) falls.
The right panel contains a sharper result.
As \(\nu \to 1\) the effective curvature \(q + \theta_X\) vanishes, and (124.10) collapses to \(\lambda \to -\delta\): the industry’s capital stock then returns to its steady state only through depreciation, with aggregate investment not responding at all.
Exercise 124.6 asks you to verify this limit and to explain it.
124.8.5. Where are we in the four regions?#
Exercise 124.1 divides the scalar model into four regions using the thresholds \(-\theta^{*}\) and \(-\theta^{**}\).
Since the technology delivers \(q + \theta_X > 0\) and an upward sloping investment supply delivers \(\theta_{\mathcal A} > 0\), this example is always in the first region.
The thresholds show how much room there is to spare.
mθ_star = q_c + δ_c*(δ_c + ρ_c)*(γ_c + θ_A_c)/δ_c**2
mθ_2star = q_c + (ρ_c/2 + δ_c)**2*(γ_c + θ_A_c)/δ_c**2

print(f"complementarity in the calibration, -θ_X = {-θ_X_c:.4f}")
print(f"instability threshold,          -θ*     = {mθ_star:.4f}")
print(f"nonexistence threshold,         -θ**    = {mθ_2star:.4f}")
complementarity in the calibration, -θ_X = 0.0919
instability threshold,          -θ*     = 0.4594
nonexistence threshold,         -θ**    = 0.4681
Complementarity would have to be five times stronger than the technology implies before the industry’s capital stock stopped converging.
124.8.6. Transition paths#
Finally, let’s trace out the industry’s response to a capital stock that starts ten percent above its steady state.
Aggregate investment follows from (124.7), which in the scalar case gives \(\mathcal A(t) = \frac{\lambda + \delta}{\delta}X(t)\).
t_c = np.linspace(0, 25, 300)
X0_c = 0.10

fig, axes = plt.subplots(1, 2, figsize=(11, 4.2))
for label in ('no interactions', 'equilibrium', 'planner (both doubled)'):
    tx, ta = cases[label]
    λ_case = scalar_lambda(ρ_c, δ_c, δ_c, q_c, γ_c, tx, ta)
    path = X0_c*np.exp(λ_case*t_c)
    axes[0].plot(t_c, 100*path, lw=2, label=label)
    axes[1].plot(t_c, 100*(λ_case + δ_c)/δ_c*path, lw=2, label=label)

axes[0].set_ylabel('capital, % above steady state')
axes[1].set_ylabel('investment, % above steady state')
for ax in axes:
    ax.set_xlabel('years')
    ax.axhline(0, color='k', lw=0.8)
axes[0].legend()
plt.tight_layout()
plt.show()
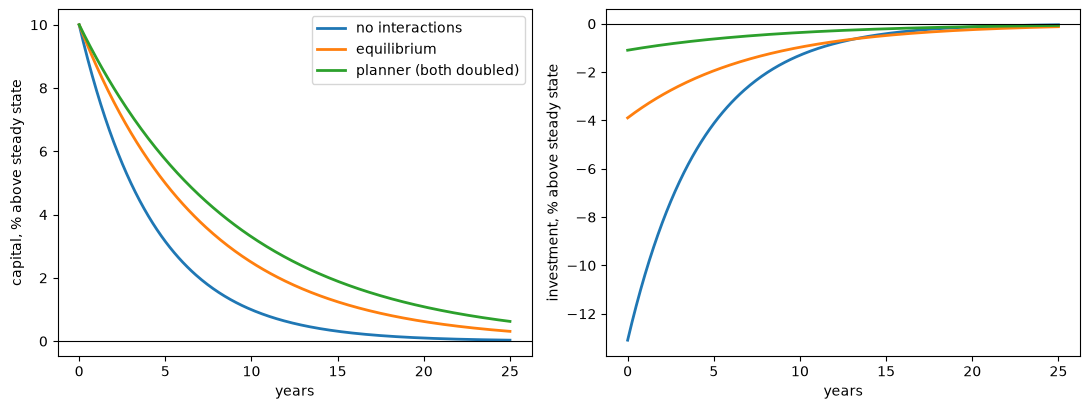
Fig. 124.2 Transition paths of capital and investment#
The right panel is the industry’s investment response, and it is where the two interactions show up most clearly.
A firm that ignored the industry would cut investment on impact by thirteen percent of its steady-state level; in equilibrium the cut is under four percent, and it is undone much more slowly.
The costate \(\beta_1(t) + \bar\beta_2 x\) that supports these paths is the marginal value of installed capital, that is, Tobin’s \(q\).
Optimal Growth Under Uncertainty and Tobin’s q studies that object in a setting where the constraint \(i \geq 0\) binds and the value function is not differentiable everywhere, which is exactly the nonlinearity that the quadratic approximation here sets aside.
124.9. Persistence#
How do the interactions change aggregate adjustment when \(n > 1\)?
Stronger complementarity of either kind makes the stabilizing solution \(P\) less negative definite.
That ordering is not enough to sign the change in every eigenvalue of the closed-loop matrix, but it does sign the change in their sum.
Stronger complementarity in states raises the trace of the closed-loop matrix, while stronger complementarity in actions lowers it.
The trace measures the rate at which a set of initial aggregate states contracts in volume as each point follows its equilibrium path, so in a stable equilibrium the first force slows the collapse toward the steady state and the second speeds it up.
print(f"{'scale on Θ_X':>14}{'trace':>10}   eigenvalues")
for scale in (0.0, 0.5, 1.0, 1.5):
    P_s = mfg_riccati(A, B, Q + scale*Θ_X, Γ + Θ_A, ρ)
    JG_s = closed_loop(A, B, Γ + Θ_A, P_s)
    print(f"{scale:>14}{np.trace(JG_s):>10.4f}   {np.linalg.eigvals(JG_s).real.round(4)}")
  scale on Θ_X     trace   eigenvalues
           0.0   -1.7933   [-0.9956 -0.7977]
           0.5   -1.6747   [-0.9485 -0.7262]
           1.0   -1.5448   [-0.9025 -0.6423]
           1.5   -1.3988   [-0.857  -0.5418]
Raising the scale makes \(\Theta_X\) more negative, that is, complementarity stronger, and the trace rises as claimed.
Exercise 124.2 asks you to investigate whether each eigenvalue must move in the same direction.
124.10. The planner#
A utilitarian planner internalizes the effect of each agent’s state and action on the corresponding cross-sectional averages.
When \(\Theta_X\) and \(\Theta_{\mathcal A}\) are symmetric, differentiating the planner’s objective doubles each interaction term.
Proposition 124.5
The planner’s allocation coincides with the decentralized equilibrium of an economy whose interaction matrices are \(2\Theta_X\) and \(2\Theta_{\mathcal A}\), so the planner’s Riccati equation is
Internalizing state complementarity makes the allocation more persistent, while internalizing action complementarity makes it less persistent.
When both are present the comparison is ambiguous, as Exercise 124.3 explores.
P_planner = mfg_riccati(A, B, Q + 2*Θ_X, Γ + 2*Θ_A, ρ)
JG_planner = closed_loop(A, B, Γ + 2*Θ_A, P_planner)

print("equilibrium eigenvalues:", np.linalg.eigvals(JG).real.round(4))
print("planner eigenvalues:    ", np.linalg.eigvals(JG_planner).real.round(4))
equilibrium eigenvalues: [-0.9025 -0.6423]
planner eigenvalues:     [-0.7786 -0.4039]
Let’s see what this means for the path of the aggregate state.
X0 = np.array([1.0, 0.5])
times = np.linspace(0, 12, 200)

paths = {'no interactions': G, 'equilibrium': JG, 'planner': JG_planner}

fig, ax = plt.subplots(figsize=(8, 4.5))
for label, M in paths.items():
    traj = np.array([expm(M*t) @ X0 for t in times])
    ax.plot(times, traj[:, 0], lw=2, label=label)
ax.set_xlabel('$t$')
ax.set_ylabel('first component of $X(t)$')
ax.legend()
plt.tight_layout()
plt.show()
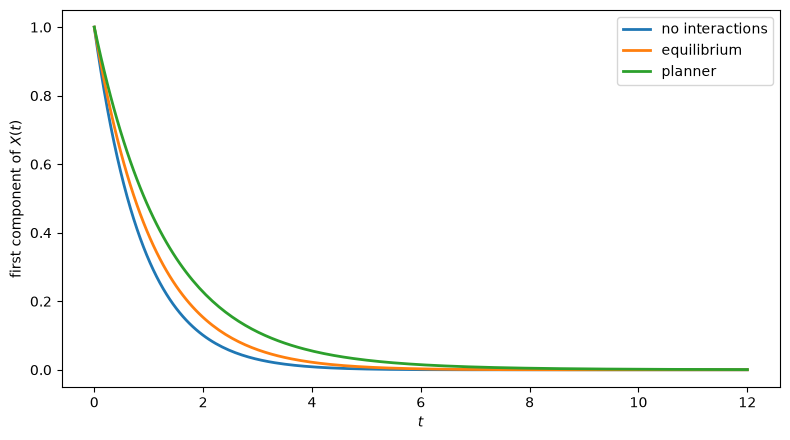
Fig. 124.3 Path of the aggregate state#
124.11. Multiproduct price setting with Kimball demand#
Our second example is multidimensional, and it delivers a surprise.
Alvarez and Argente [2026] study a continuum of “stores”, each selling \(n\) products with constant marginal costs \(z_j\).
Products within a store are aggregated by a CES price index with elasticity \(\bar\eta_d\), and stores are aggregated by a symmetric Kimball aggregator [Kimball, 1995].
Let \(\eta_D(y)\) be the elasticity of a store’s demand with respect to its relative price, and let \(\bar\eta_D > 1\) and \(\bar\eta_D'\) denote its level and its derivative at the symmetric point.
The derivative \(\bar\eta_D'\) is the superelasticity of demand, and it is the reason Kimball demand is so widely used in models of price setting: a positive superelasticity means that a store which raises its prices above the average faces a more elastic demand, which discourages it from moving away from the crowd.
That is strategic complementarity in prices, and it is the mechanism that Klenow and Willis [2016] and much of the subsequent literature rely on for real rigidity.
Writing \(x\) and \(X\) for log deviations of a store’s prices and of the average store’s prices from the flexible-price level \(\bar p_i = \bar z_i \bar\eta_D/(\bar\eta_D-1)\), and \(\bar s\) for the vector of steady-state expenditure shares, the curvature matrices are
Stare at the third line.
The superelasticity appears in \(Q\) and in \(\Theta_X\), but it cancels from \(Q + \Theta_X\).
By Proposition 124.2, the sum \(Q+\Theta_X\) is the only channel through which either matrix reaches aggregate dynamics.
Actions are the rates of change of prices, and stores pay quadratic Rotemberg costs of changing them.
The matrix \(\Gamma\) lets that cost depend on which bundle of prices is changed, with negative off-diagonal elements representing economies of scope in repricing of the kind emphasized by Midrigan [2011] and Alvarez and Lippi [2014].
There is no interaction through aggregate actions, so \(\Theta_{\mathcal A} = 0\), and a nonzero rate of cost inflation makes \(A\) diagonal.
def kimball(η_d, η_D, η_D_prime, s):
    "Curvature and state-interaction matrices under Kimball demand."
    s = np.asarray(s, dtype=float)
    S = np.outer(s, s)
    Q = (η_D - 1)*((η_D - η_d + η_D_prime/(η_D - 1))*S + η_d*np.diag(s))
    Θ_X = -η_D_prime*S
    return Q, Θ_X

s_bar = np.array([0.5, 0.3, 0.2])       # three products, unequal shares
η_d, η_D = 6.0, 4.0                     # within-store and across-store elasticities
ρ_K, π_K = 0.04, 0.02                   # discount rate and cost inflation

n_K = len(s_bar)
A_K = π_K*np.eye(n_K)
B_K = np.eye(n_K)
Γ_K = 20.0*(np.eye(n_K) - 0.25*(np.ones((n_K, n_K)) - np.eye(n_K)))

print("Rotemberg cost matrix Γ =\n", Γ_K)
print("\neigenvalues of Γ:", np.linalg.eigvalsh(Γ_K).round(4))
Rotemberg cost matrix Γ =
 [[20. -5. -5.]
 [-5. 20. -5.]
 [-5. -5. 20.]]

eigenvalues of Γ: [10. 25. 25.]
124.11.1. The superelasticity and aggregate dynamics#
Now sweep the superelasticity across a wide range, including a negative value, and watch what changes and what does not.
print(f"{'η_D′':>6}  {'eigenvalues of Q':>28}  {'eigenvalues of Q + Θ_X':>28}")
for η_Dp in (-3.0, 0.0, 3.0, 10.0):
    Q_K, Θ_K = kimball(η_d, η_D, η_Dp, s_bar)
    print(f"{η_Dp:>6}  {str(np.linalg.eigvalsh(Q_K).round(3)):>28}"
          f"  {str(np.linalg.eigvalsh(Q_K + Θ_K).round(3)):>28}")
  η_D′              eigenvalues of Q        eigenvalues of Q + Θ_X
  -3.0           [2.598 4.5   7.482]           [3.127 4.766 7.827]
   0.0           [3.127 4.766 7.827]           [3.127 4.766 7.827]
   3.0           [3.435 5.096 8.329]           [3.127 4.766 7.827]
  10.0        [ 3.714  5.694 10.112]           [3.127 4.766 7.827]
The own-curvature matrix \(Q\) moves a great deal, and \(\Theta_X\) moves with it, but the effective curvature does not move at all.
Aggregate price dynamics are therefore invariant to the superelasticity.
print(f"{'η_D′':>6}  {'aggregate eigenvalues':>34}  {'individual eigenvalues':>34}")
for η_Dp in (-3.0, 0.0, 3.0, 10.0):
    Q_K, Θ_K = kimball(η_d, η_D, η_Dp, s_bar)
    P_K = mfg_riccati(A_K, B_K, Q_K + Θ_K, Γ_K, ρ_K)
    β2_K = mfg_riccati(A_K, B_K, Q_K, Γ_K, ρ_K)
    ev_agg = np.sort(np.linalg.eigvals(closed_loop(A_K, B_K, Γ_K, P_K)).real)
    ev_ind = np.sort(np.linalg.eigvals(closed_loop(A_K, B_K, Γ_K, β2_K)).real)
    print(f"{η_Dp:>6}  {str(ev_agg.round(4)):>34}  {str(ev_ind.round(4)):>34}")
  η_D′               aggregate eigenvalues              individual eigenvalues
  -3.0           [-0.6527 -0.4882 -0.3836]           [-0.5813 -0.4752 -0.3815]
   0.0           [-0.6527 -0.4882 -0.3836]           [-0.6527 -0.4882 -0.3836]
   3.0           [-0.6527 -0.4882 -0.3836]           [-0.7234 -0.4928 -0.3844]
  10.0           [-0.6527 -0.4882 -0.3836]           [-0.8713 -0.4966 -0.3853]
The left block of numbers is identical in every row, and the right block is not.
The superelasticity changes how an individual store behaves without changing how the industry behaves.
Almost all of the movement is in a single mode, because \(\Theta_X\) is rank one and points in the direction \(\bar s\), which is the store’s own share-weighted price index.
The remaining modes, which involve relative prices within the store, barely move.
124.11.2. Static complementarity#
It is worth seeing how much static complementarity we are varying.
Maximizing the static profit function gives the best response \(x^{*}(X) = -Q^{-1}\Theta_X X\), and Alvarez and Argente [2026] show that
print(f"{'η_D′':>6}{'pass-through':>14}   best response matrix, first row")
for η_Dp in (-3.0, 0.0, 3.0, 10.0):
    Q_K, Θ_K = kimball(η_d, η_D, η_Dp, s_bar)
    BR = -np.linalg.solve(Q_K, Θ_K)
    κ = η_Dp/((η_D - 1)*η_D)
    BR_closed = κ/(1 + κ)*np.outer(np.ones(n_K), s_bar)
    assert np.allclose(BR, BR_closed)
    print(f"{η_Dp:>6}{BR.sum(axis=1)[0]:>14.4f}   {BR[0].round(4)}")

print("\nΘ_X symmetric:      ", np.allclose(Θ_K, Θ_K.T))
print("best response symmetric:", np.allclose(BR, BR.T))
  η_D′  pass-through   best response matrix, first row
  -3.0       -0.3333   [-0.1667 -0.1    -0.0667]
   0.0        0.0000   [0. 0. 0.]
   3.0        0.2000   [0.1  0.06 0.04]
  10.0        0.4545   [0.2273 0.1364 0.0909]

Θ_X symmetric:       True
best response symmetric: False
Static pass-through runs from \(-33\%\) to \(+45\%\) across these rows, and it changes sign with the superelasticity, yet every one of these economies has exactly the same aggregate dynamics.
An intuition that reads stronger static complementarity as more aggregate propagation is therefore unreliable.
Notice also that the best response matrix is not symmetric, because shares differ across products, while \(\Theta_X\) always is.
Symmetry of \(\Theta_X\) is what Proposition 124.5 needs, and it survives even when the static game looks asymmetric.
124.11.3. Closed-form eigenvalues#
Because \(A_K\) is a multiple of the identity and \(B_K = I\), the aggregate eigenvalues have the same form as in the scalar case, one for each eigenvalue \(\omega_i\) of \((\Gamma+\Theta_{\mathcal A})^{-1}(Q+\Theta_X)\):
Q_K, Θ_K = kimball(η_d, η_D, 3.0, s_bar)
P_K = mfg_riccati(A_K, B_K, Q_K + Θ_K, Γ_K, ρ_K)
JG_K = closed_loop(A_K, B_K, Γ_K, P_K)

ω = np.linalg.eigvals(np.linalg.solve(Γ_K, Q_K + Θ_K)).real
predicted = np.sort(ρ_K/2 - np.sqrt((ρ_K/2 + π_K)**2 + ω))

print("eigenvalues of the closed-loop matrix:", np.sort(np.linalg.eigvals(JG_K).real).round(6))
print("from the closed-form formula:         ", predicted.round(6))
eigenvalues of the closed-loop matrix: [-0.652659 -0.488188 -0.383578]
from the closed-form formula:          [-0.652659 -0.488188 -0.383578]
Exercise 124.8 asks what happens when inflation differs across products, so that \(A\) is diagonal but not a multiple of the identity.
124.11.4. Aggregate and individual price paths#
The decomposition (124.17) splits a store’s prices into the industry average \(X\) and its own deviation \(z = x - X\).
The first follows the equilibrium matrix \(P\), the second the single-agent matrix \(\bar\beta_2\).
So the invariance we found should show up as identical paths for the industry and different paths for a store that is out of line.
t_K = np.linspace(0, 8, 200)
shock = 0.10*np.ones(n_K)      # ten percent above target, all products

fig, axes = plt.subplots(1, 2, figsize=(11, 4.2))
for k, η_Dp in enumerate((-3.0, 0.0, 3.0, 10.0)):
    Q_K, Θ_K = kimball(η_d, η_D, η_Dp, s_bar)
    P_K = mfg_riccati(A_K, B_K, Q_K + Θ_K, Γ_K, ρ_K)
    β2_K = mfg_riccati(A_K, B_K, Q_K, Γ_K, ρ_K)
    U_XX = closed_loop(A_K, B_K, Γ_K, P_K)
    U_zz = closed_loop(A_K, B_K, Γ_K, β2_K)
    agg = np.array([s_bar @ expm(U_XX*t) @ shock for t in t_K])
    dev = np.array([s_bar @ expm(U_zz*t) @ shock for t in t_K])
    label = f"$\\bar\\eta_D' = {η_Dp}$"
    # decreasing line widths, so that four coincident curves remain visible
    axes[0].plot(t_K, 100*agg, lw=6 - 1.5*k, label=label)
    axes[1].plot(t_K, 100*dev, lw=2, label=label)

axes[0].set_title('industry price index, $\\bar s^\\top X(t)$')
axes[1].set_title("one store's deviation, $\\bar s^\\top z(t)$")
for ax in axes:
    ax.set_xlabel('years')
    ax.set_ylabel('percent above target')
    ax.legend()
plt.tight_layout()
plt.show()
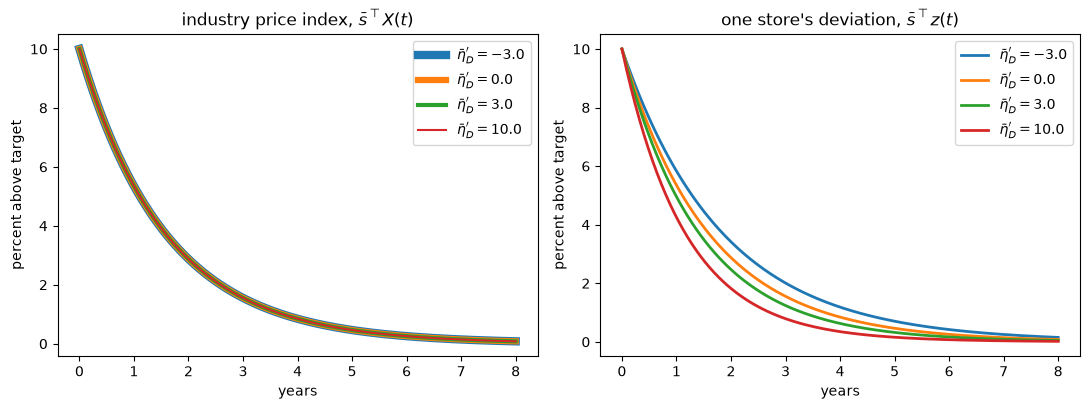
Fig. 124.4 Industry and store price paths#
The four curves in the left panel lie exactly on top of one another.
The four curves in the right panel do not: the higher the superelasticity, the faster a store closes a gap between its own prices and the industry’s.
Micro and macro price flexibility are governed by different objects, and only the micro one responds to the superelasticity.
124.11.5. The planner does care#
Doubling the interaction gives the planner the effective curvature \(Q + 2\Theta_X = (Q + \Theta_X) - \bar\eta_D' \bar s\bar s^\top\), which does depend on the superelasticity.
print(f"{'η_D′':>6}  {'eig(Q + 2Θ_X)':>26}  {'planner eigenvalues':>32}")
for η_Dp in (-3.0, 0.0, 3.0, 10.0, 20.0):
    Q_K, Θ_K = kimball(η_d, η_D, η_Dp, s_bar)
    M = Q_K + 2*Θ_K
    P_p = mfg_riccati(A_K, B_K, M, Γ_K, ρ_K)
    ev = np.sort(np.linalg.eigvals(closed_loop(A_K, B_K, Γ_K, P_p)).real)
    flag = "" if np.linalg.eigvalsh(M).min() > 0 else "   <- not positive definite"
    print(f"{η_Dp:>6}  {str(np.linalg.eigvalsh(M).round(3)):>26}"
          f"  {str(ev.round(4)):>32}{flag}")
  η_D′               eig(Q + 2Θ_X)               planner eigenvalues
  -3.0         [3.435 5.096 8.329]         [-0.7234 -0.4928 -0.3844]
   0.0         [3.127 4.766 7.827]         [-0.6527 -0.4882 -0.3836]
   3.0         [2.598 4.5   7.482]         [-0.5813 -0.4752 -0.3815]
  10.0         [0.654 4.211 7.054]         [-0.5132 -0.3931 -0.2383]
  20.0      [-2.788  4.092  6.816]         [-0.5055 -0.3881  8.4685]   <- not positive definite
So the equilibrium’s insensitivity to the superelasticity is special to the equilibrium.
The gap between what a planner would do and what the industry does widens as the superelasticity rises, and in the last row the planner’s effective curvature has stopped being positive definite and the returned matrix no longer stabilizes the system.
Exercise 124.7 locates the threshold exactly, and gives it an interpretation in terms of static pass-through.
124.12. Aggregate shocks and identification#
Now add a shock that hits everyone at once.
Let \(\mathcal J\) be a compensated jump process and suppose
With common noise the value function must keep track of the aggregate state as well as the individual state, so it becomes \(v(x, X)\).
Nevertheless, matching coefficients in the recursive HJB equation delivers a result worth emphasizing.
Proposition 124.6
With common noise, the matrix \(P\) governing aggregate dynamics solves the same equilibrium Riccati equation as before.
This is a certainty-equivalence result of the kind familiar from linear quadratic control.
It also yields a clean decomposition.
Writing \(z = x - X\) for an agent’s deviation from the cross-sectional mean,
Look carefully at the second line.
The dynamics of an agent’s deviation from the mean involve \(\bar\beta_2\), the solution of the single-agent Riccati equation, and neither interaction matrix appears.
The same is true of the part of the action that responds to \(z\).
Proposition 124.7
Data on \(x(t) - X(t)\) and \(\alpha(t)-\mathcal A(t)\) contain no information about \(\Theta_X\) or \(\Theta_{\mathcal A}\).
This is a sharp statement of the “missing intercept” problem.
Removing time effects from micro data – a standard way to control for aggregate conditions – removes exactly the variation that identifies strategic interaction.
Aggregate data, by contrast, do carry that information, and can be combined with micro data to recover it.
# reduced-form matrices that an econometrician could estimate
U_XX = closed_loop(A, B, Γ + Θ_A, P)            # drift of the aggregate state
U_zz = closed_loop(A, B, Γ, β2)                 # drift of the deviation from the mean

print("aggregate drift U_XX =\n", U_XX.round(4))
print("\ndeviation drift U_zz =\n", U_zz.round(4))

# now double the state interaction and recompute
P_alt = mfg_riccati(A, B, Q + 2*Θ_X, Γ + Θ_A, ρ)
print("\nwith Θ_X doubled:")
print("  aggregate drift changes: ",
      not np.allclose(U_XX, closed_loop(A, B, Γ + Θ_A, P_alt)))
print("  deviation drift changes: ",
      not np.allclose(U_zz, closed_loop(A, B, Γ, β2)))
aggregate drift U_XX =
 [[-0.8403 -0.178 ]
 [-0.0692 -0.7045]]

deviation drift U_zz =
 [[-1.0597 -0.1326]
 [-0.0174 -0.8423]]

with Θ_X doubled:
  aggregate drift changes:  True
  deviation drift changes:  False
Exercise 124.4 shows how to recover \(\Theta_X\) from aggregate data, and why \(\Theta_X\) and \(\Theta_{\mathcal A}\) cannot be told apart without a normalization.
124.13. Exercises#
Exercise 124.1
Formulas (124.11) and (124.12) divide the scalar model into four regions.
Define
Take \(\rho = 0.5\), \(a = 0.3\), \(b = 1\), \(q = 1\), \(\gamma = 1\), \(\theta_{\mathcal A}=0\).
Compute \(\theta^{*}\) and \(\theta^{**}\), and verify that \(-\theta^{**} = -\theta^{*} + (\rho/2)^2(\gamma+\theta_{\mathcal A})/b^2\).
For values of \(\theta_X\) on either side of each threshold, compute \(\lambda\) and classify the outcome: stable, a unit root, divergent but admissible, or no equilibrium.
What does
mfg_riccatido when no equilibrium exists?Plot \(\lambda\) against \(\theta_X\) and mark the thresholds.
Solution
ρ_e, a_e, b_e, q_e, γ_e, θA_e = 0.5, 0.3, 1.0, 1.0, 1.0, 0.0

θ_star = -(q_e + a_e*(a_e + ρ_e)*(γ_e + θA_e)/b_e**2)
θ_ss = -(q_e + (ρ_e/2 + a_e)**2*(γ_e + θA_e)/b_e**2)

print(f"θ*  = {θ_star:.4f}")
print(f"θ** = {θ_ss:.4f}")
print(f"gap = {θ_star - θ_ss:.4f}, "
      f"(ρ/2)²(γ+θ_A)/b² = {(ρ_e/2)**2*(γ_e + θA_e)/b_e**2:.4f}")
θ*  = -1.2400
θ** = -1.3025
gap = 0.0625, (ρ/2)²(γ+θ_A)/b² = 0.0625
for θ_X in (0.5, -0.5, θ_star, -1.27, -1.31):
    inside = (ρ_e/2 + a_e)**2 + b_e**2*(q_e + θ_X)/(γ_e + θA_e)
    if inside < 0:
        print(f"θ_X = {θ_X:+.4f}: no equilibrium")
        continue
    λ = ρ_e/2 - np.sqrt(inside)
    if λ < -1e-9:
        kind = "stable, X converges to zero"
    elif abs(λ) <= 1e-9:
        kind = "unit root, X stays where it starts"
    else:
        kind = "divergent but admissible"
    print(f"θ_X = {θ_X:+.4f}: λ = {λ:+.5f}   {kind}")
θ_X = +0.5000: λ = -1.09257   stable, X converges to zero
θ_X = -0.5000: λ = -0.64582   stable, X converges to zero
θ_X = -1.2400: λ = -0.00000   unit root, X stays where it starts
θ_X = -1.2700: λ = +0.06972   divergent but admissible
θ_X = -1.3100: no equilibrium
Below \(\theta^{**}\) there is no real root, and the solver reports failure rather than returning a spurious answer.
try:
    mfg_riccati(np.array([[a_e]]), np.array([[b_e]]),
                np.array([[q_e - 1.31]]), np.array([[γ_e]]), ρ_e)
except Exception as e:
    print(f"solver raises {type(e).__name__} when no equilibrium exists")
solver raises LinAlgError when no equilibrium exists
θ_grid = np.linspace(-1.30, 0.5, 400)
inside = (ρ_e/2 + a_e)**2 + b_e**2*(q_e + θ_grid)/(γ_e + θA_e)
λ_grid = np.where(inside >= 0, ρ_e/2 - np.sqrt(np.maximum(inside, 0)), np.nan)

fig, ax = plt.subplots(figsize=(8, 4.5))
ax.plot(θ_grid, λ_grid, lw=2)
ax.axhline(0, color='k', lw=0.8)
ax.axhline(ρ_e/2, color='grey', ls=':', lw=1, label=r'$\rho/2$')
ax.axvline(θ_star, color='r', ls='--', lw=1, label=r'$\theta^{*}$')
ax.axvline(θ_ss, color='b', ls='--', lw=1, label=r'$\theta^{**}$')
ax.set_xlabel(r'$\theta_X$')
ax.set_ylabel(r'$\lambda$')
ax.legend()
plt.tight_layout()
plt.show()
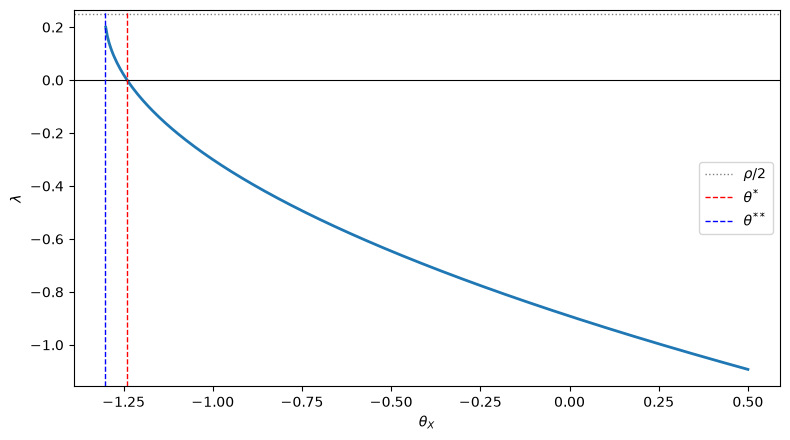
Moving left along the horizontal axis means stronger complementarity in states.
Persistence rises smoothly until \(\theta^{*}\), where the aggregate state stops converging; between \(\theta^{*}\) and \(\theta^{**}\) equilibrium paths diverge, though slowly enough to keep discounted payoffs finite; below \(\theta^{**}\) no equilibrium exists at all.
Exercise 124.2
The lecture showed that stronger complementarity in states raises the trace of the closed-loop matrix.
Does it also raise every eigenvalue?
Draw many random two-dimensional economies: take \(B = I\), let \(Q\) and \(\Gamma\) be random positive definite matrices, let \(\Theta_X\) be random negative definite, and set \(\rho = 0.05\).
For each draw, compare the equilibrium with interaction \(\Theta_X\) to the one with \(1.5\,\Theta_X\), keeping only draws in which both equilibria exist and are admissible.
Report how often the trace rises and how often every eigenvalue rises.
Solution
rng = np.random.default_rng(3)
trace_rose = eig_rose = kept = 0

for _ in range(400):
    A_r = rng.normal(size=(2, 2))*0.3 + 0.4*np.eye(2)
    B_r = np.eye(2)
    M = rng.normal(size=(2, 2)); Q_r = M @ M.T + 0.5*np.eye(2)
    M = rng.normal(size=(2, 2)); Γ_r = M @ M.T + 0.5*np.eye(2)
    M = rng.normal(size=(2, 2)); Θ_r = -0.2 * (M @ M.T)

    try:
        P0 = mfg_riccati(A_r, B_r, Q_r + Θ_r, Γ_r, 0.05)
        P1 = mfg_riccati(A_r, B_r, Q_r + 1.5*Θ_r, Γ_r, 0.05)
    except Exception:
        continue

    J0 = closed_loop(A_r, B_r, Γ_r, P0)
    J1 = closed_loop(A_r, B_r, Γ_r, P1)
    if max(np.linalg.eigvals(J0).real.max(), np.linalg.eigvals(J1).real.max()) >= 0.025:
        continue

    kept += 1
    trace_rose += np.trace(J1) > np.trace(J0) - 1e-10
    e0 = np.sort(np.linalg.eigvals(J0).real)
    e1 = np.sort(np.linalg.eigvals(J1).real)
    eig_rose += np.all(e1 >= e0 - 1e-10)

print(f"admissible draws:            {kept}")
print(f"trace rose:                  {trace_rose}/{kept}")
print(f"every eigenvalue rose:       {eig_rose}/{kept}")
admissible draws:            347
trace rose:                  345/347
every eigenvalue rose:       293/347
The trace result holds in every draw, as the theory says it must.
Eigenvalue-by-eigenvalue monotonicity fails in a noticeable minority of cases.
The reason is that \(Q+\Theta_X\) and \(B(\Gamma+\Theta_{\mathcal A})^{-1}B^\top\) need not commute, so the problem does not separate into independent one-dimensional problems, and a change that slows adjustment overall can still speed it up along some direction.
Additional restrictions – for instance a scalar drift matrix \(A = a I\) – restore monotonicity mode by mode.
Exercise 124.3
Compare the planner with the decentralized equilibrium.
Using the two-dimensional example from the lecture, compute the eigenvalues of the closed-loop matrix for the equilibrium and for the planner in four cases:
only complementarity in states, \(\Theta_X \prec 0\) and \(\Theta_{\mathcal A}=0\)
only substitutability in actions, \(\Theta_X = 0\) and \(\Theta_{\mathcal A} = 0.2 I\)
only complementarity in actions, \(\Theta_X = 0\) and \(\Theta_{\mathcal A} = -0.2 I\)
complementarity in both
In which cases is the planner’s allocation more persistent than the equilibrium? Explain.
Solution
def eigen_pair(Θ_X_use, Θ_A_use):
    "Closed-loop eigenvalues for the equilibrium and for the planner."
    P_eq = mfg_riccati(A, B, Q + Θ_X_use, Γ + Θ_A_use, ρ)
    P_pl = mfg_riccati(A, B, Q + 2*Θ_X_use, Γ + 2*Θ_A_use, ρ)
    e_eq = np.sort(np.linalg.eigvals(closed_loop(A, B, Γ + Θ_A_use, P_eq)).real)
    e_pl = np.sort(np.linalg.eigvals(closed_loop(A, B, Γ + 2*Θ_A_use, P_pl)).real)
    return e_eq, e_pl

zero = np.zeros((2, 2))
cases = {'states, complements':  (Θ_X, zero),
         'actions, substitutes': (zero,  0.2*np.eye(2)),
         'actions, complements': (zero, -0.2*np.eye(2)),
         'both complements':     (Θ_X, -0.2*np.eye(2))}

print(f"{'case':24}{'equilibrium':>22}{'planner':>22}   planner slower?")
for label, (tx, ta) in cases.items():
    e_eq, e_pl = eigen_pair(tx, ta)
    slower = bool(np.all(e_pl >= e_eq - 1e-12))
    print(f"{label:24}{str(e_eq.round(4)):>22}{str(e_pl.round(4)):>22}   {slower}")
case                               equilibrium               planner   planner slower?
states, complements          [-0.9584 -0.673 ]     [-0.8522 -0.4287]   True
actions, substitutes         [-0.9933 -0.7741]     [-0.9344 -0.7284]   True
actions, complements         [-1.1748 -0.9088]     [-1.3325 -1.0151]   False
both complements             [-1.0426 -0.7346]     [-1.0137 -0.4958]   True
With only complementarity in states, the planner’s allocation is more persistent.
The planner recognizes that when one agent stays away from the steady state, others are content to stay away too, so there is less reason to hurry back.
With only complementarity in actions, the comparison reverses and the planner adjusts faster: the planner internalizes that when one agent adjusts, others want to adjust as well.
The case of substitutability in actions is the mirror image of the last one, and again makes the planner slower.
When complementarity is present in both states and actions, the two forces work against each other.
In this calibration the state interaction dominates and the planner is still slower, but that ranking is a quantitative accident, not a theorem: in general the comparison between planner and equilibrium persistence cannot be signed.
Exercise 124.4
This exercise works through Proposition 124.7 and its consequences.
Verify that the drift of an agent’s deviation from the cross-sectional mean is unchanged when \(\Theta_X\) and \(\Theta_{\mathcal A}\) change.
Suppose an econometrician knows \(\rho\), \(Q\), \(A\), \(B\), \(\Gamma\) and \(\Theta_{\mathcal A}\), and estimates the aggregate drift matrix \(U_{\dot X, X}\). Show how to recover \(\Theta_X\), and verify your procedure numerically.
In the scalar model, show that \(\theta_X\) and \(\theta_{\mathcal A}\) are not separately identified: construct a family of pairs that generate identical aggregate dynamics and identical policy coefficients.
Solution
For part 1, the deviation drift is \(B\Gamma^{-1}B^\top\bar\beta_2 - A\), and \(\bar\beta_2\) solves the single-agent Riccati equation (124.6), in which no interaction matrix appears.
for label, (tx, ta) in {'baseline': (Θ_X, Θ_A),
                        'very different': (3*Θ_X, -0.1*np.eye(2))}.items():
    β2_case = mfg_riccati(A, B, Q, Γ, ρ)        # does not depend on tx, ta
    print(f"{label:16}: U_zz =", closed_loop(A, B, Γ, β2_case).round(6).tolist())
baseline        : U_zz = [[-1.059657, -0.132645], [-0.017424, -0.842298]]
very different  : U_zz = [[-1.059657, -0.132645], [-0.017424, -0.842298]]
For part 2, invert the definition of the closed-loop matrix to get \(P\), then read \(\Theta_X\) off the equilibrium Riccati equation:
U_obs = closed_loop(A, B, Γ + Θ_A, P)      # what the econometrician estimates

P_hat = np.linalg.solve(Λ, U_obs + A)
Θ_X_hat = P_hat @ Λ @ P_hat - Q - ρ*P_hat - P_hat @ A - A.T @ P_hat

print("true Θ_X =\n", Θ_X.round(6))
print("\nrecovered Θ_X =\n", Θ_X_hat.round(6))
print(f"\nmaximum error: {np.abs(Θ_X - Θ_X_hat).max():.2e}")
true Θ_X =
 [[-0.3   0.05]
 [ 0.05 -0.2 ]]

recovered Θ_X =
 [[-0.3   0.05]
 [ 0.05 -0.2 ]]

maximum error: 1.67e-16
For part 3, formula (124.10) shows that \(\lambda\) depends on the two interactions only through the ratio \((q+\theta_X)/(\gamma+\theta_{\mathcal A})\).
Holding that ratio fixed traces out a one-parameter family of observationally equivalent economies.
The policy coefficient cannot break the tie, because \(\lambda = b\,U_{\alpha,X} - a\) ties it to \(\lambda\).
ratio = (q + (-0.4))/(γ + 0.3)       # baseline θ_X = -0.4, θ_A = 0.3

print(f"{'θ_A':>7}{'θ_X':>12}{'λ':>12}{'policy coeff':>15}")
for θ_A_alt in (0.3, 0.0, 0.6, 1.0):
    θ_X_alt = ratio*(γ + θ_A_alt) - q
    λ_alt = scalar_lambda(ρ_s, a, b, q, γ, θ_X_alt, θ_A_alt)
    print(f"{θ_A_alt:>7.2f}{θ_X_alt:>12.6f}{λ_alt:>12.6f}{(λ_alt + a)/b:>15.6f}")
    θ_A         θ_X           λ   policy coeff
   0.30   -0.400000   -0.728103      -0.428103
   0.00   -0.538462   -0.728103      -0.428103
   0.60   -0.261538   -0.728103      -0.428103
   1.00   -0.076923   -0.728103      -0.428103
Every row describes a different economy, with a different amount of strategic complementarity in states and in actions, yet all of them generate exactly the same aggregate dynamics and the same policy rule.
Distinguishing them requires normalizing one interaction, or bringing outside information to bear.
Exercise 124.5
This exercise derives the two curvatures that we simply assumed when calibrating the capital accumulation example.
Suppose the adjustment cost is
so that \(\psi'(\bar i) = 0\) and \(\psi''(\bar i) = \phi/\bar i\), and suppose investment goods are supplied with constant elasticity \(\varepsilon_s\),
Use the steady-state Euler equation \(\Pi_k(\bar k, \bar k) = \rho + \delta\) to show that \(\bar k^{1-\nu} = \nu(\eta-1)/[\eta(\rho+\delta)]\), and then that
Which \((\phi, \varepsilon_s)\) reproduce the calibration \(\gamma = 0.05\) and \(\theta_{\mathcal A} = 0.09\)?
Show that all pairs with the same value of \(\phi + 1/\varepsilon_s\) generate identical aggregate dynamics, and verify numerically that they nevertheless imply different individual investment rules and different planner allocations.
Solution
For part 1, \(\Pi_k(k,K) = \nu\frac{\eta-1}{\eta}k^{\nu(1-1/\eta)-1}K^{\nu/\eta}\), so on the diagonal \(\Pi_k(\bar k,\bar k) = \nu\frac{\eta-1}{\eta}\bar k^{\nu-1}\).
Setting this equal to \(\rho+\delta\), which is the steady-state user cost when \(\mathcal P(\bar i) = 1\) and \(\psi'(\bar i) = 0\), gives the stated expression for \(\bar k^{1-\nu}\).
Since \(\bar\Pi = \bar k^{\nu}\) and \(\bar i = \delta\bar k\),
scale_c = δ_c*ν_c*(η_c - 1)/(η_c*(ρ_c + δ_c))      # δ k̄^{1-ν}

print(f"δ k̄^(1-ν) = {scale_c:.4f}")
print(f"φ   implied by γ = {γ_c}:   {γ_c/scale_c:.4f}")
print(f"ε_s implied by θ_A = {θ_A_c}: {scale_c/θ_A_c:.4f}")
δ k̄^(1-ν) = 0.3500
φ   implied by γ = 0.05:   0.1429
ε_s implied by θ_A = 0.09: 3.8889
The calibration corresponds to a moderately convex adjustment cost, \(\phi = 0.14\), and an investment supply elasticity of about \(3.9\).
For part 3, \(\gamma + \theta_{\mathcal A} = \delta\bar k^{1-\nu}(\phi + 1/\varepsilon_s)\), and by (124.10) only this sum matters for \(\lambda\).
But the individual’s Riccati equation (124.6) involves \(\gamma\) alone, and the planner’s involves \(\gamma + 2\theta_{\mathcal A}\), so both separate the pairs.
print(f"{'φ':>6}{'1/ε_s':>8}{'aggregate':>12}{'individual':>12}{'planner':>10}")
for φ, inv_ε in ((0.40, 0.00), (0.30, 0.10), (1/7, 0.257143), (0.05, 0.35)):
    γ_case, θ_A_case = φ*scale_c, inv_ε*scale_c
    λ_agg = scalar_lambda(ρ_c, δ_c, δ_c, q_c, γ_case, θ_X_c, θ_A_case)
    λ_ind = scalar_lambda(ρ_c, δ_c, δ_c, q_c, γ_case, 0.0, 0.0)
    λ_pl = scalar_lambda(ρ_c, δ_c, δ_c, q_c, γ_case, 2*θ_X_c, 2*θ_A_case)
    print(f"{φ:>6.3f}{inv_ε:>8.3f}{λ_agg:>12.6f}{λ_ind:>12.6f}{λ_pl:>10.4f}")
     φ   1/ε_s   aggregate  individual   planner
 0.400   0.000   -0.138936   -0.157859   -0.1175
 0.300   0.100   -0.138936   -0.173431   -0.1142
 0.143   0.257   -0.138936   -0.230930   -0.1109
 0.050   0.350   -0.138936   -0.372649   -0.1096
Aggregate dynamics are identical down to the last digit, while individual behavior ranges from sluggish to almost frictionless.
An econometrician with only aggregate data cannot tell a congested market for capital goods from an expensive installation technology, which is the scalar version of Proposition 124.7.
Exercise 124.6
The right panel of the figure above suggests that something special happens as returns to scale approach constancy.
Show that \(q + \theta_X \to 0\) and \(\lambda \to -\delta\) as \(\nu \to 1\), for every \(\eta > 1\).
Show that the response of aggregate investment to a capital gap, \((\lambda+\delta)/\delta\), goes to zero in the same limit.
Explain the limit in economic terms.
Solution
Part 1 is immediate from (124.14): \(q + \theta_X = \frac{\eta-1}{\eta}\nu(1-\nu) \to 0\), and with \(a = b = \delta\),
For part 2, the scalar version of (124.7) gives \(\mathcal A = \frac{\lambda+\delta}{\delta}X\), which vanishes as \(\lambda \to -\delta\).
print(f"{'ν':>8}{'q + θ_X':>10}{'λ':>10}{'half-life':>11}{'A/X':>9}")
for ν in (0.7, 0.9, 0.99, 0.999, 0.99999):
    λ_ν = scalar_lambda(ρ_c, δ_c, δ_c, cap_q(η_c, ν), γ_c, cap_θ_X(η_c, ν), θ_A_c)
    print(f"{ν:>8}{cap_q(η_c,ν) + cap_θ_X(η_c,ν):>10.5f}{λ_ν:>10.5f}"
          f"{half_life(λ_ν):>11.3f}{(λ_ν + δ_c)/δ_c:>9.4f}")
       ν   q + θ_X         λ  half-life      A/X
     0.7   0.15750  -0.13894      4.989  -0.3894
     0.9   0.06750  -0.11799      5.875  -0.1799
    0.99   0.00743  -0.10210      6.789  -0.0210
   0.999   0.00075  -0.10021      6.917  -0.0021
 0.99999   0.00001  -0.10000      6.931  -0.0000
For part 3, note that \(q + \theta_X = -\bar k^2\left[\Pi_{kk} + \Pi_{kK}\right]/\bar\Pi\) measures the curvature of profit along the diagonal, that is, the rate at which the marginal profitability of capital falls when the whole industry expands together.
With \(\nu = 1\) the profit function (124.13) is homogeneous of degree one in \((k, K)\) jointly, so \(\Pi_k(k,k)\) does not depend on \(k\) at all.
An industry-wide capital gap then creates no incentive to invest differently, and the gap closes only through depreciation.
Effective curvature is zero, the economy sits exactly on the boundary of the existence region in (124.11), and the equilibrium remains unique and stable with \(\lambda = -\delta\).
Exercise 124.7
In the Kimball example, the equilibrium’s effective curvature \(Q + \Theta_X\) is positive definite for every superelasticity, but the planner’s, \(Q + 2\Theta_X\), is not.
Using \(Q + 2\Theta_X = (Q+\Theta_X) - \bar\eta_D'\,\bar s\bar s^\top\), show that it is positive definite if and only if \(\bar\eta_D'\,\bar s^\top(Q+\Theta_X)^{-1}\bar s < 1\).
Show that \((Q+\Theta_X)\mathbb{1} = (\bar\eta_D-1)\bar\eta_D\,\bar s\), where \(\mathbb{1}\) is a vector of ones, and hence that the condition is \(\bar\eta_D' < (\bar\eta_D-1)\bar\eta_D\).
Show that this is exactly the condition that static pass-through in (124.16) be below one half, and verify the threshold numerically.
Solution
For part 1, if \(\bar\eta_D' \leq 0\) the rank-one term is added rather than subtracted and positive definiteness is immediate.
If \(\bar\eta_D' > 0\), then for \(M \succ 0\) the matrix \(M - c vv^\top\) with \(c>0\) is positive definite if and only if \(c\, v^\top M^{-1}v < 1\), which follows from the determinant identity \(\det(M - cvv^\top) = \det(M)(1 - c\,v^\top M^{-1}v)\) applied to every leading block, or directly from the Schur complement of the bordered matrix.
For part 2, using \(\bar s^\top\mathbb{1} = 1\) in the third line of (124.15),
So \((Q+\Theta_X)^{-1}\bar s = \mathbb{1}/[(\bar\eta_D-1)\bar\eta_D]\) and therefore
which turns the condition in part 1 into \(\bar\eta_D' < (\bar\eta_D-1)\bar\eta_D\).
For part 3, that inequality says precisely that \(\kappa < 1\), and \(\kappa/(1+\kappa)\) is increasing in \(\kappa\) with value \(1/2\) at \(\kappa = 1\).
Total static pass-through is \(\sum_j \partial x_i^{*}/\partial X_j = \kappa/(1+\kappa)\) because the shares sum to one, so the planner’s problem is well behaved exactly when a store would pass less than half of an industry-wide price increase into its own prices.
lo, hi = 0.0, 100.0
for _ in range(60):
    mid = (lo + hi)/2
    Q_m, Θ_m = kimball(η_d, η_D, mid, s_bar)
    if np.linalg.eigvalsh(Q_m + 2*Θ_m).min() > 0:
        lo = mid
    else:
        hi = mid

κ_star = lo/((η_D - 1)*η_D)
print(f"threshold by bisection:  η_D′ = {lo:.6f}")
print(f"(η_D - 1) η_D         =        {(η_D - 1)*η_D:.6f}")
print(f"κ at the threshold    = {κ_star:.6f}")
print(f"pass-through there    = {κ_star/(1 + κ_star):.6f}")
threshold by bisection:  η_D′ = 12.000000
(η_D - 1) η_D         =        12.000000
κ at the threshold    = 1.000000
pass-through there    = 0.500000
Exercise 124.8
The closed-form eigenvalues in the Kimball example used \(A = \pi I\).
Replace it by \(A = \operatorname{diag}(0.00, 0.02, 0.06)\), so that the three products face different rates of cost inflation.
Check that the closed-form formula fails.
Check that the trace comparative static of the Persistence section still holds, by scaling \(\Theta_X\) and recording the trace and the eigenvalues of the closed-loop matrix.
Does the invariance of aggregate dynamics to the superelasticity survive?
Solution
A_het = np.diag([0.00, 0.02, 0.06])
Q_h, Θ_h = kimball(η_d, η_D, 3.0, s_bar)

P_h = mfg_riccati(A_het, B_K, Q_h + Θ_h, Γ_K, ρ_K)
JG_h = closed_loop(A_het, B_K, Γ_K, P_h)

ω_h = np.linalg.eigvals(np.linalg.solve(Γ_K, Q_h + Θ_h)).real
print("closed-loop eigenvalues:", np.sort(np.linalg.eigvals(JG_h).real).round(5))
print("closed-form formula:    ",
      np.sort(ρ_K/2 - np.sqrt((ρ_K/2 + np.diag(A_het))**2 + np.sort(ω_h))).round(5))
closed-loop eigenvalues: [-0.6519  -0.48847 -0.38891]
closed-form formula:     [-0.65622 -0.48819 -0.38209]
The formula no longer holds: with \(A\) not a multiple of the identity there is no single scalar shift to put inside the square root, and the eigenvectors of \(A\) and of \(Q+\Theta_X\) need not agree.
The errors are modest here because the three inflation rates are close together, but they are systematic, and they grow with the dispersion in \(A\).
The trace result, on the other hand, requires no such restriction.
print(f"{'scale on Θ_X':>14}{'trace':>10}   eigenvalues")
for scale in (0.0, 0.5, 1.0, 1.5):
    P_s = mfg_riccati(A_het, B_K, Q_h + scale*Θ_h, Γ_K, ρ_K)
    JG_s = closed_loop(A_het, B_K, Γ_K, P_s)
    print(f"{scale:>14}{np.trace(JG_s):>10.5f}   "
          f"{np.sort(np.linalg.eigvals(JG_s).real).round(5)}")
  scale on Θ_X     trace   eigenvalues
           0.0  -1.60539   [-0.723   -0.49291 -0.38948]
           0.5  -1.56838   [-0.68798 -0.49116 -0.38924]
           1.0  -1.52928   [-0.6519  -0.48847 -0.38891]
           1.5  -1.48769   [-0.6153  -0.48399 -0.3884 ]
Raising the scale strengthens complementarity and raises the trace, exactly as in the two-dimensional example earlier.
For part 3, the invariance has nothing to do with \(A\): it comes from the cancellation of \(\bar\eta_D'\) in \(Q + \Theta_X\), and Proposition 124.2 shows that only \(Q+\Theta_X\) and \(\Gamma+\Theta_{\mathcal A}\) enter the equilibrium Riccati equation.
for η_Dp in (-3.0, 0.0, 3.0, 10.0):
    Q_i, Θ_i = kimball(η_d, η_D, η_Dp, s_bar)
    P_i = mfg_riccati(A_het, B_K, Q_i + Θ_i, Γ_K, ρ_K)
    ev = np.sort(np.linalg.eigvals(closed_loop(A_het, B_K, Γ_K, P_i)).real)
    print(f"η_D′ = {η_Dp:>5}:  {ev.round(6)}")
η_D′ =  -3.0:  [-0.651898 -0.488473 -0.388911]
η_D′ =   0.0:  [-0.651898 -0.488473 -0.388911]
η_D′ =   3.0:  [-0.651898 -0.488473 -0.388911]
η_D′ =  10.0:  [-0.651898 -0.488473 -0.388911]
124.14. Further reading#
Alvarez and Argente [2026] develop the results in this lecture, along with the two economic examples that we implemented above.
They also extend the analysis to interactions through higher moments of the cross-sectional distribution.
Carmona and Delarue [2018] give a comprehensive probabilistic treatment of mean field games, and Achdou et al. [2022] describe the numerical methods used to solve the coupled partial differential equations when the model is not linear quadratic.